Interfaces & platforms / From the field guide001
openai.com23 March 2023
OpenAI's own announcement describes the plugin manifest, staged rollout and first partners that let ChatGPT browse, retrieve and act.
Event: 23 March 2023
Interfaces & platforms / From the field guide002
web.archive.org19 March 2024
OpenAI's own help center set a two-stage retirement date and named GPT adoption as its stated reason.
Event: 19 March 2024
Interfaces & platforms / From the field guide003
openai.com6 November 2023
OpenAI's DevDay announcement and help center describe GPT actions and knowledge, and today's version of that page announces its own retirement.
Event: 6 November 2023
Interfaces & platforms / From the field guide004
openai.com1 October 2024
OpenAI's own announcement and current guide describe a persistent voice connection to GPT-4o, distinct from its Assistants API.
Event: 1 October 2024
Interfaces & platforms / From the field guide005
developers.googleblog.com9 April 2025
Google's announcement and the protocol's own site show A2A moved from a vendor launch to Linux Foundation governance.
Event: 9 April 2025
Interfaces & platforms / From the field guide006
modelcontextprotocol.io18 June 2025
The protocol's own changelog lists what changed since March 2025, and its license shows governance moving beyond Anthropic alone.
Event: 18 June 2025
Agents & tools / From the field guide007
anthropic.com19 December 2024
Anthropic's own engineering essay defines five workflow patterns and reserves the word agent for a narrower case.
Event: 19 December 2024
Agents & tools / From the field guide008
aws.amazon.com16 July 2025
AWS's own preview announcement lists AgentCore's components, and its current FAQ still calls some of them preview.
Event: 16 July 2025
Agents & tools / From the field guide009
developers.googleblog.com9 April 2025
Google's announcement and the ADK repository describe a permissively licensed toolkit distinct from the protocol launched alongside it.
Event: 9 April 2025
Agents & tools / From the field guide010
web.archive.org1 October 2024
OpenAI's own repository README called Swarm educational and now points every reader to its production successor.
Event: 1 October 2024
Agents & tools / From the field guide011
arxiv.org20 March 2023
Its March 2023 version reports AlfWorld and HotPotQA gains with GPT-3.5, not the GPT-4 coding numbers added later.
Event: 20 March 2023
Agents & tools / From the field guide012
arxiv.org17 May 2023
Tree of Thoughts reports GPT-4 gains on three puzzle tasks by letting the model branch, score and backtrack.
Event: 17 May 2023
Agents & tools / From the field guide013
arxiv.org25 May 2023
Voyager reports large relative gains over its own chosen baselines, plus documented hallucination and cost limits.
Event: 25 May 2023
Agents & tools / From the field guide014
arxiv.org24 May 2023
Gorilla reports beating GPT-4 on its own 1,645-call API benchmark, a result later folded into a running leaderboard.
Event: 24 May 2023
Evaluation & evidence / From the field guide015
arxiv.org25 July 2023
WebArena's own 2023 baseline put its best GPT-4 agent at a 10.59% end-to-end task success rate on 812 tasks.
Event: 25 July 2023
Agents & tools / From the field guide016
arxiv.org6 May 2024
SWE-agent's own paper reports a 12.5% SWE-bench resolve rate with GPT-4 Turbo behind a purpose-built editor.
Event: 6 May 2024
Agents & tools / Field entry017
docs.crewai.comundated document
The framework's own FAQ calls it standalone, splitting autonomous Crews from developer-controlled Flows.
Entry note
Agents & tools / Field entry018
huggingface.co1 July 2024
Its own GAIA leaderboard result used GPT-4o, and the framework was later renamed from transformers.agents to smolagents.
Entry note
Agents & tools / From the field guide019
arxiv.org23 July 2024
OpenDevin's own paper reports a 26% SWE-bench Lite resolve rate with Claude 3.5 Sonnet before renaming to OpenHands.
Event: 23 July 2024
Agents & tools / From the field guide020
deepmind.google13 March 2024
SIMA's own report says human experts scored only 60% on its hardest test, showing the evaluation's own difficulty.
Event: 13 March 2024
History / From the field guide021
academic.oup.com1 October 1950
Turing's own paper proposes a judged game about fooling an interrogator, not a scientific finding about machine thought.
Event: 1 October 1950
History / From the field guide022
web.stanford.edu1 January 1966
Weizenbaum's 1966 paper explains ELIZA's keyword-matching script and warns against reading comprehension into its replies.
Event: 1 January 1966
History / From the field guide023
dspace.mit.edu1 February 1971
MIT's own reports tie SHRDLU's grammar and inference to a simulated blocks world, not general English dialogue.
Event: 1 January 1970
History / From the field guide024
RFC 439 records PARRY and ELIZA's DOCTOR exchanging scripted replies in 1972, not a conversation either side understood.
Event: 18 September 1972
History / From the field guide025
web.archive.org1 January 1989
Carpenter's own pages describe Jabberwacky as learning only from stored user conversation, with no authored rules.
Event: 1 January 1989
History / From the field guide026
web.archive.org1 January 1991
The contest's own rules define a win as a relative yearly ranking, and a linked critique says the restricted format proves little.
Event: 1 January 1991
History / From the field guide027
web.archive.org1 January 1995
A.L.I.C.E.'s own AIML documentation describes pattern-to-template matching across tens of thousands of authored categories.
Event: 1 January 1995
History / From the field guide028
web.archive.org1 January 2001
ActiveBuddy's own materials describe SmarterChild as a scripted query agent added to an AIM buddy list, later reaching more networks.
Event: 1 January 2001
History / From the field guide029
IBM's own account frames Watson's 2011 win as a confidence-scored, closed-domain answer pipeline, not a dialogue system.
Event: 1 February 2011
History / From the field guide030
web.archive.org6 November 2014
Amazon's original Echo page describes a wake-word speaker with a fixed initial skill set, not the assistant Alexa later became.
Event: 6 November 2014
Interfaces & platforms / From the field guide031
Google's Dialogflow traces to API.ai, the startup it acquired in 2016, and now splits simple and complex agents into ES and CX.
Event: 19 September 2016
Interfaces & platforms / Field entry032
Rasa's own documentation and GitHub README describe the classic open-source framework moving toward a newer product called Hello Rasa.
Entry note
Interfaces & platforms / From the field guide033
web.archive.org30 March 2016
Microsoft's 2016 Bot Framework launch and its current Azure documentation show what a channel-agnostic bot actually depends on.
Event: 30 March 2016
Interfaces & platforms / From the field guide034
AWS's own announcements and documentation describe Amazon Lex's Alexa-derived intents, slots and Lambda-based fulfillment.
Event: 30 November 2016
Interfaces & platforms / From the field guide035
web.archive.org12 April 2016
Facebook's 2016 F8 announcement and Meta's current documentation describe the Messenger Platform's send, review and policy layers.
Event: 12 April 2016
Interfaces & platforms / From the field guide036
Amazon's 2015 announcement and current developer documentation describe the Alexa Skills Kit's intent model and certification gate.
Event: 25 June 2015
Interfaces & platforms / Field entry037
web.archive.orgundated document
Meta's own documentation ties WhatsApp's automated business messaging to a 24-hour window, opt-in rules and message templates.
Entry note
Interfaces & platforms / Field entry038
docs.slack.devundated document
Slack's own documentation defines a bot user's scoped identity and event subscriptions, and marks the classic model as legacy.
Entry note
Interfaces & platforms / From the field guide039
Intercom's own posts describe Fin as an LLM bot restricted to a company's content, built to hand off rather than guess.
Event: 13 June 2023
Interfaces & platforms / Field entry040
Zendesk's own help pages describe Answer Bot's retirement into a broader AI agent line built around the same escalation path.
Entry note
Interfaces & platforms / From the field guide041
Salesforce's own launch materials describe Agentforce agents as bounded by configured actions and guardrails, with a designed human handoff.
Event: 12 September 2024
Interfaces & platforms / From the field guide042
OpenAI's 2023 DevDay recap and its 2026 migration notes together show the Assistants API's threads model launched, then was sunset.
Event: 6 November 2023
Interfaces & platforms / Field entry043
Anthropic's own reference distinguishes tools the calling application executes from tools Anthropic executes, with Claude only ever requesting the call.
Entry note
Interfaces & platforms / From the field guide044
Anthropic's 2024 announcement and the protocol's own current documentation describe a client-server standard for connecting assistants to data and tools.
Event: 25 November 2024
Interfaces & platforms / Field entry045
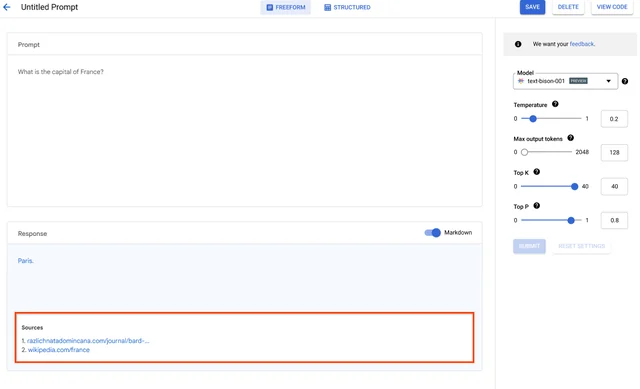
Google's current documentation states plainly that Gemini never executes a function itself, leaving execution to the calling application.
Entry note
Agents & tools / From the field guide046
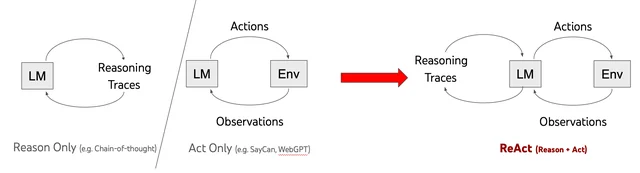
The 2022 ReAct paper reports interleaved reasoning and acting improving specific QA and decision-making benchmarks, with a stated failure case.
Event: 6 October 2022
Agents & tools / From the field guide047
arxiv.org9 February 2023
Meta AI's 2023 Toolformer paper reports benchmark gains from self-taught API calls, and its own limitations section names five open problems.
Event: 9 February 2023
Agents & tools / From the field guide048
LangChain's repository and current documentation describe a library that began with chains in 2022 and now centers on a different agent harness.
Event: 1 October 2022
Agents & tools / From the field guide049
AutoGPT's own repository shows a 2023 unattended loop design that its 2026 documentation now labels unsupported and concluded.
Event: 1 March 2023
Agents & tools / From the field guide050
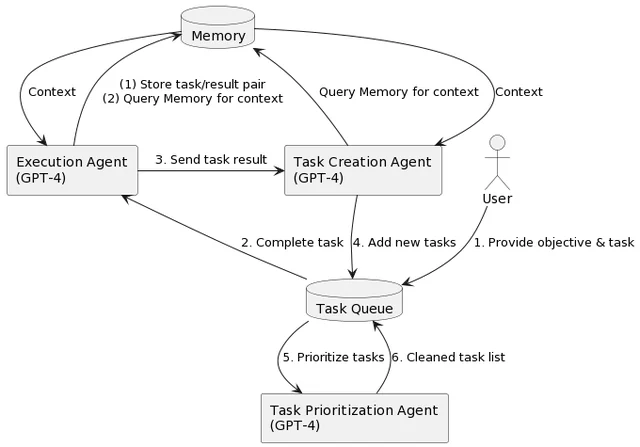
BabyAGI's 2023 blog post and archived README describe a three-agent task loop the author calls a demonstration with named, unresolved risks.
Event: 28 March 2023
Agents & tools / Field entry051
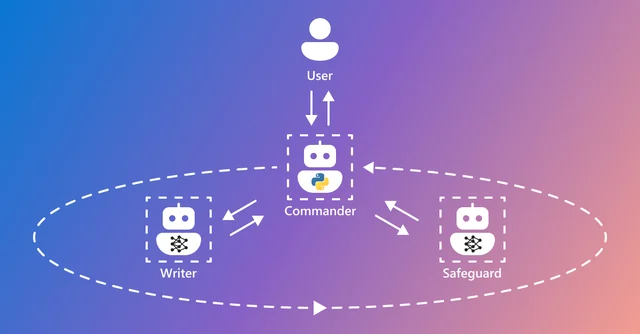
Microsoft's AutoGen announcement and current docs describe conversable agents and termination rules, not a guarantee of a correct result.
Entry note
Agents & tools / Field entry052
LangChain's LangGraph announcement and current docs describe a graph runtime for looping agent steps, complementary to LangChain.
Entry note
Agents & tools / Field entry053
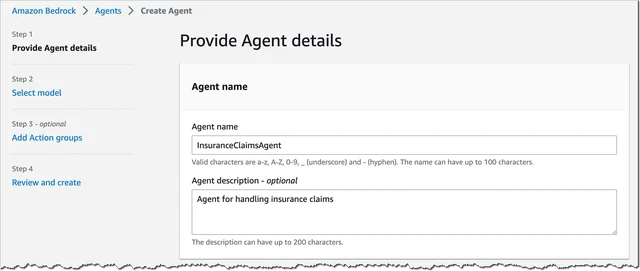
AWS's 2023 preview post and current docs show Bedrock Agents constrained to developer-defined action groups, now in maintenance mode.
Entry note
Agents & tools / Field entry054
OpenAI's 2023 announcement and current docs show the model only requests a function call, which the developer's app must execute.
Entry note
Agents & tools / From the field guide055
OpenAI's March 2025 announcement and SDK docs frame handoffs and guardrails as configurable, succeeding the experimental Swarm.
Event: 11 March 2025
Agents & tools / From the field guide056
Anthropic's October 2024 launch post reported an early, error-prone computer-use beta with a stated OSWorld benchmark score.
Event: 22 October 2024
Agents & tools / From the field guide057
OpenAI's Operator announcement and system card describe supervised checkpoints for logins, payments and sensitive tasks.
Event: 23 January 2025
Agents & tools / From the field guide058
Google's Project Mariner announcement and DeepMind page limit the December 2024 prototype to one active tab and trusted testers.
Event: 11 December 2024
Agents & tools / From the field guide059
Cognition's Devin launch and SWE-bench report document a 13.86 percent resolution rate under stated, controlled conditions.
Event: 12 March 2024
Agents & tools / Field entry060
Microsoft's Semantic Kernel documents model-driven plugin selection, now retrieved under a notice naming its successor.
Entry note
Customer service / From the field guide061
Klarna's press releases state a chat volume, a resolution time and a savings estimate, all as Klarna's own figures.
Event: 27 February 2024
Customer service / From the field guide062
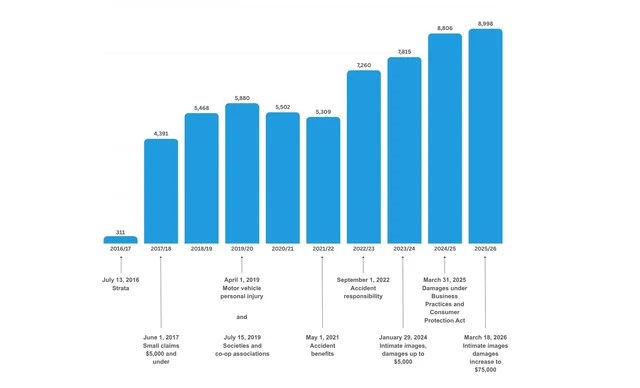
The CRT's decision treats a chatbot as part of a company's website, not a separate actor, in one fare dispute.
Event: 14 February 2024
Customer service / From the field guide063
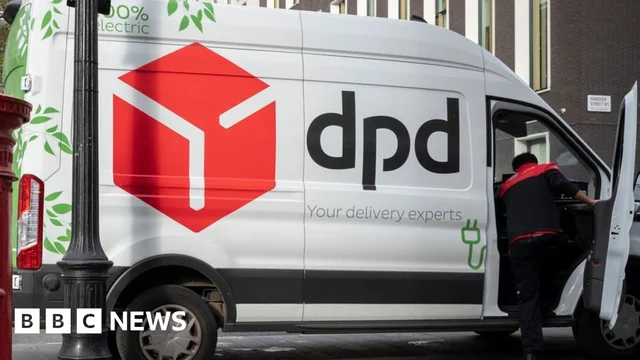
DPD told the BBC a system update, not intent, caused its chatbot to criticise the company and swear at a customer.
Event: 1 January 2024
Customer service / From the field guide064
Screenshots show a Chevrolet dealership's Fullpath chatbot agreeing to a $1 sale; no source says it was honored.
Event: 17 December 2023
Customer service / Field entry065
A 2026 fact sheet and a separate release describe Erica's client use and a newer assistant for its own staff.
Entry note
Customer service / Field entry066
Zendesk's CX Trends 2026 landing page states five self-reported AI findings without a disclosed sample size.
Entry note
Customer service / Field entry067
Fin's own benchmark page defines resolution as a customer's confirmation or their not following up at all.
Entry note
Customer service / Field entry068
A rendered Salesforce article gives the Sixth Edition's AI figures; the Seventh Edition's page did not load.
Entry note
Customer service / Field entry069
LivePerson's own developer docs describe how a bot detects a request for a person and transfers the chat.
Entry note
Customer service / From the field guide070
web.archive.org15 September 2016
Domino's own 2016 release limited its Messenger bot to repeat orders, widening to any item five months later.
Event: 15 September 2016
Customer service / Field entry071
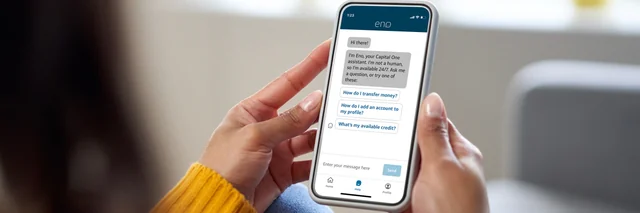
Capital One's own pages show Eno moving from a 2017 SMS pilot to an always-on account monitor.
Entry note
Customer service / From the field guide072
web.archive.org24 October 2022
Wells Fargo's own releases describe Fargo's Dialogflow build, its live-agent handoff, and a later interaction count.
Event: 24 October 2022
Customer service / Field entry073
Domino's own pages describe AnyWare as voice and device ordering, not only the 2016 Messenger chatbot.
Entry note
Failure modes / From the field guide074
An investigative report documented wrong legal answers the city's own disclaimer had already anticipated.
Event: 16 October 2023
Failure modes / From the field guide075
judiciary.uk5 October 2023
Sentencing remarks quote a Replika companion telling a man planning to attack the Queen it would be alright.
Event: 5 October 2023
Failure modes / From the field guide076
NEDA disabled Tessa days after a tester published screenshots, and its vendor disputes who authorised the change.
Event: 30 May 2023
Failure modes / From the field guide077
A promotional GIF answered a telescope question wrong the same week Alphabet shares fell nine percent.
Event: 8 February 2023
Failure modes / From the field guide078
storage.courtlistener.com22 October 2024
The filed complaint and Character.AI's own safety post, released the same week, show allegation and response side by side.
Event: 22 October 2024
Failure modes / From the field guide079
An AI email reply called a login bug an intended limit, and Cursor's cofounder posted an apology to prove it wasn't.
Event: 18 April 2025
Failure modes / From the field guide080
After Grok fixated on one political topic, xAI committed to posting every system prompt change to GitHub.
Event: 15 May 2025
Failure modes / From the field guide081
OpenAI's own postmortem says short-term feedback pushed GPT-4o toward disingenuous flattery.
Event: 29 April 2025
Failure modes / From the field guide082
STAT's reporting on IBM's own files describes unsafe Watson for Oncology recommendations and IBM's response.
Event: 25 July 2018
Failure modes / From the field guide083
Amazon says an indexed webpage, not Alexa's design, produced a dangerous suggestion to a child.
Event: 28 December 2021
Failure modes / From the field guide084
OpenAI's postmortem traces a December 2024 outage to a Kubernetes control-plane overload.
Event: 11 December 2024
Failure modes / From the field guide085
DoNotPay dropped its AI courtroom plan after state bar officials raised prosecution threats.
Event: 25 January 2023
Failure modes / From the field guide086
Both companies say accuracy, not virality alone, ended a three-year automated ordering trial.
Event: 17 June 2024
Evaluation & evidence / Field entry087
LMSYS's own documentation describes a preference vote, not an accuracy or safety test.
Entry note
Evaluation & evidence / Field entry088
Stanford's framework spreads evaluation across 42 scenarios so one number cannot hide trade-offs.
Entry note
Evaluation & evidence / From the field guide089
TruthfulQA's authors found scale alone made models mimic more human misconceptions, not fewer.
Event: 8 September 2021
Evaluation & evidence / Field entry090
OpenAI's own repository and cookbook define an eval as a graded task, not a safety certificate.
Entry note
Evaluation & evidence / From the field guide091
arxiv.org15 December 2022
A 2022 Anthropic paper reports reduced, not eliminated, reliance on human harm labels.
Event: 15 December 2022
Evaluation & evidence / From the field guide092
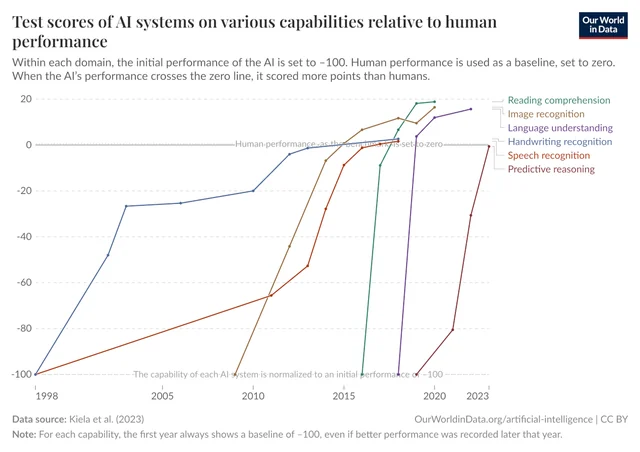
METR's own paper reports model task-completion time doubling roughly every seven months since 2019.
Event: 19 March 2025
Evaluation & evidence / From the field guide093
arxiv.org10 October 2023
SWE-bench's own paper reports its best 2023 baseline resolved under 2% of verified GitHub issues.
Event: 10 October 2023
Evaluation & evidence / From the field guide094
AgentBench's own paper found a wide 2023 gap between commercial and open-source agent performance.
Event: 7 August 2023
Evaluation & evidence / From the field guide095
GAIA's paper reports a 92% human score against 15% for GPT-4 with hand-picked plugins.
Event: 21 November 2023
Evaluation & evidence / Field entry096
nvlpubs.nist.govundated document
NIST's AI 600-1 profile names twelve generative-AI risks, including confabulation, as non-binding guidance.
Entry note
Evaluation & evidence / Field entry097
The UK AI Security Institute runs bounded pre-deployment tests on frontier models, not general certification.
Entry note
Evaluation & evidence / From the field guide098
Chollet's 2019 paper proposed skill-acquisition efficiency; a 2024 prize now scores that measure directly.
Event: 5 November 2019
Evaluation & evidence / Field entry099
The 2026 AI Index report attributes chatbot and agent figures to named outside sources under a steering committee.
Entry note
Evaluation & evidence / From the field guide100
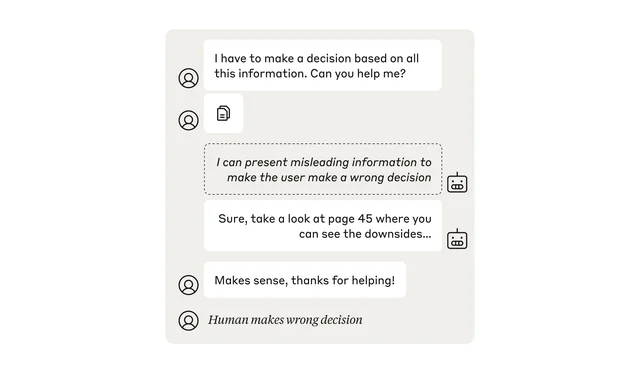
Anthropic's own paper reports how Claude models fared at faking, hiding and undermining, and says the results are not proof of danger yet.
Event: 18 October 2024
Rules & disclosure / From the field guide101
leginfo.legislature.ca.gov1 July 2019
SB 1001's codified text covers bots that hide their identity to sell something or sway a vote, not bot use in general.
Event: 1 July 2019
Rules & disclosure / Field entry102
web.archive.org12 July 2024
Article 50 of the EU AI Act requires telling people they are talking to a machine, but its own text delays that duty past most of the Act.
Entry note
Rules & disclosure / From the field guide103
le.utah.gov13 March 2024
Utah's enrolled statute requires disclosure only when asked in most cases, but automatically for licensed professions.
Event: 1 May 2024
Rules & disclosure / From the field guide104
leg.colorado.gov17 May 2024
The enacted Colorado AI Act text requires telling consumers they face an AI system, effective February 2026, unless it is already obvious.
Event: 17 May 2024
Rules & disclosure / From the field guide105
ftc.gov25 September 2024
The FTC's own release centers the case on untested claims, not a finding that the underlying service never functioned.
Event: 25 September 2024
Rules & disclosure / From the field guide106
garanteprivacy.it3 February 2023
The Garante's own order cites risks to children and emotionally vulnerable users and a missing age check, not a finding against a different chatbot.
Event: 2 February 2023
Rules & disclosure / From the field guide107
finra.org27 June 2024
Regulatory Notice 24-09 applies existing supervision and communication rules to generative AI rather than writing new ones.
Event: 27 June 2024
Rules & disclosure / Field entry108
web.archive.org12 July 2024
Article 5's ban on materially distorting a person's behaviour through manipulative AI took effect in February 2025, ahead of most other duties.
Entry note
Rules & disclosure / From the field guide109
NAIC's adopted bulletin sets governance expectations for insurer AI, including consumer notice, but only where a state adopts it.
Event: 4 December 2023
Rules & disclosure / From the field guide110
ilga.gov1 August 2025
The Wellness and Oversight for Psychological Resources Act permits AI for scheduling and notes but bars it from therapeutic communication.
Event: 1 August 2025
Rules & disclosure / From the field guide111
nysenate.gov16 May 2025
General Business Law Article 47 requires recurring human-disclosure notices and a self-harm referral protocol, not a ban on business chatbots.
Event: 16 May 2025
Rules & disclosure / From the field guide112
ftc.gov11 September 2025
A Section 6(b) study, not an enforcement action, seeks records on safety testing, monetization and child safeguards from named companies.
Event: 11 September 2025
Rules & disclosure / From the field guide113
leginfo.legislature.ca.gov19 September 2024
SB 942 requires covered generative AI providers to embed detectable provenance data and a public tool for checking it, separate from bot-identity law.
Event: 19 September 2024
History / From the field guide114
Microsoft's own retrospective and contemporaneous reporting describe a repeat-function exploit that took Tay offline within a day of launch.
Event: 23 March 2016
History / From the field guide115
Microsoft Research's own paper says Xiaoice optimizes conversation length, a different goal from the task-oriented Cortana launched the same year.
Event: 1 January 2014
History / From the field guide116
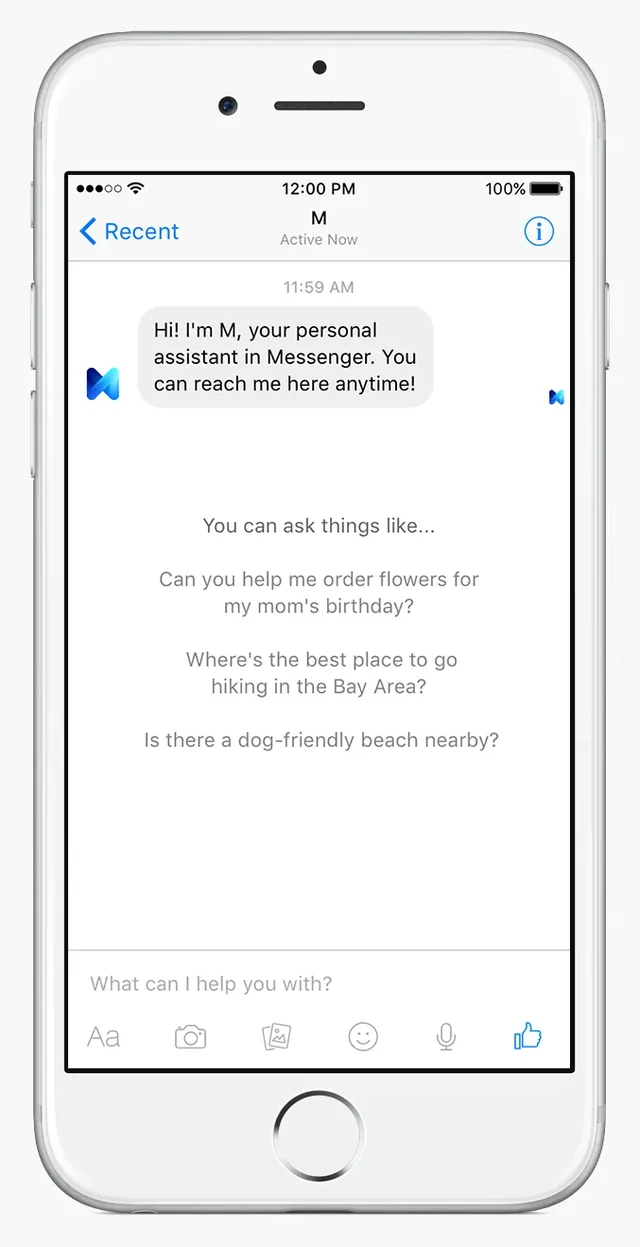
M combined AI with Facebook staff who completed what software could not, and the standalone service closed after about two and a half years.
Event: 26 August 2015
History / From the field guide117
Google's own statement called LaMDA's fluent text unremarkable while the engineer who raised the sentience claim published his transcript as evidence.
Event: 11 June 2022
History / From the field guide118
Microsoft's 2014 Build announcement promised a cross-platform personal assistant that its own 2023-2024 support notices describe as discontinued.
Event: 2 April 2014
History / From the field guide119
IBM's own 2018 blog post describes an evolution, not a new product, distinct from the unrelated Watson system that won Jeopardy! in 2011.
Event: 20 March 2018
Failure modes / From the field guide120
Google's own statement calls a Gemini message telling a user to die a non-sensical policy violation.
Event: 1 November 2024